KERNELS · LIVE
Reads GGUF directly
A bounds-checked GGUF v2/v3 reader memory-maps the whole file read-only. Every read is checked, so a broken file fails cleanly.
GGUF V2 · V3FISH is a C++ engine that runs GGUF language models on ordinary computers. No llama.cpp underneath: every kernel, the tokenizer and the planner are ours.
A bounds-checked GGUF v2/v3 reader memory-maps the whole file read-only. Every read is checked, so a broken file fails cleanly.
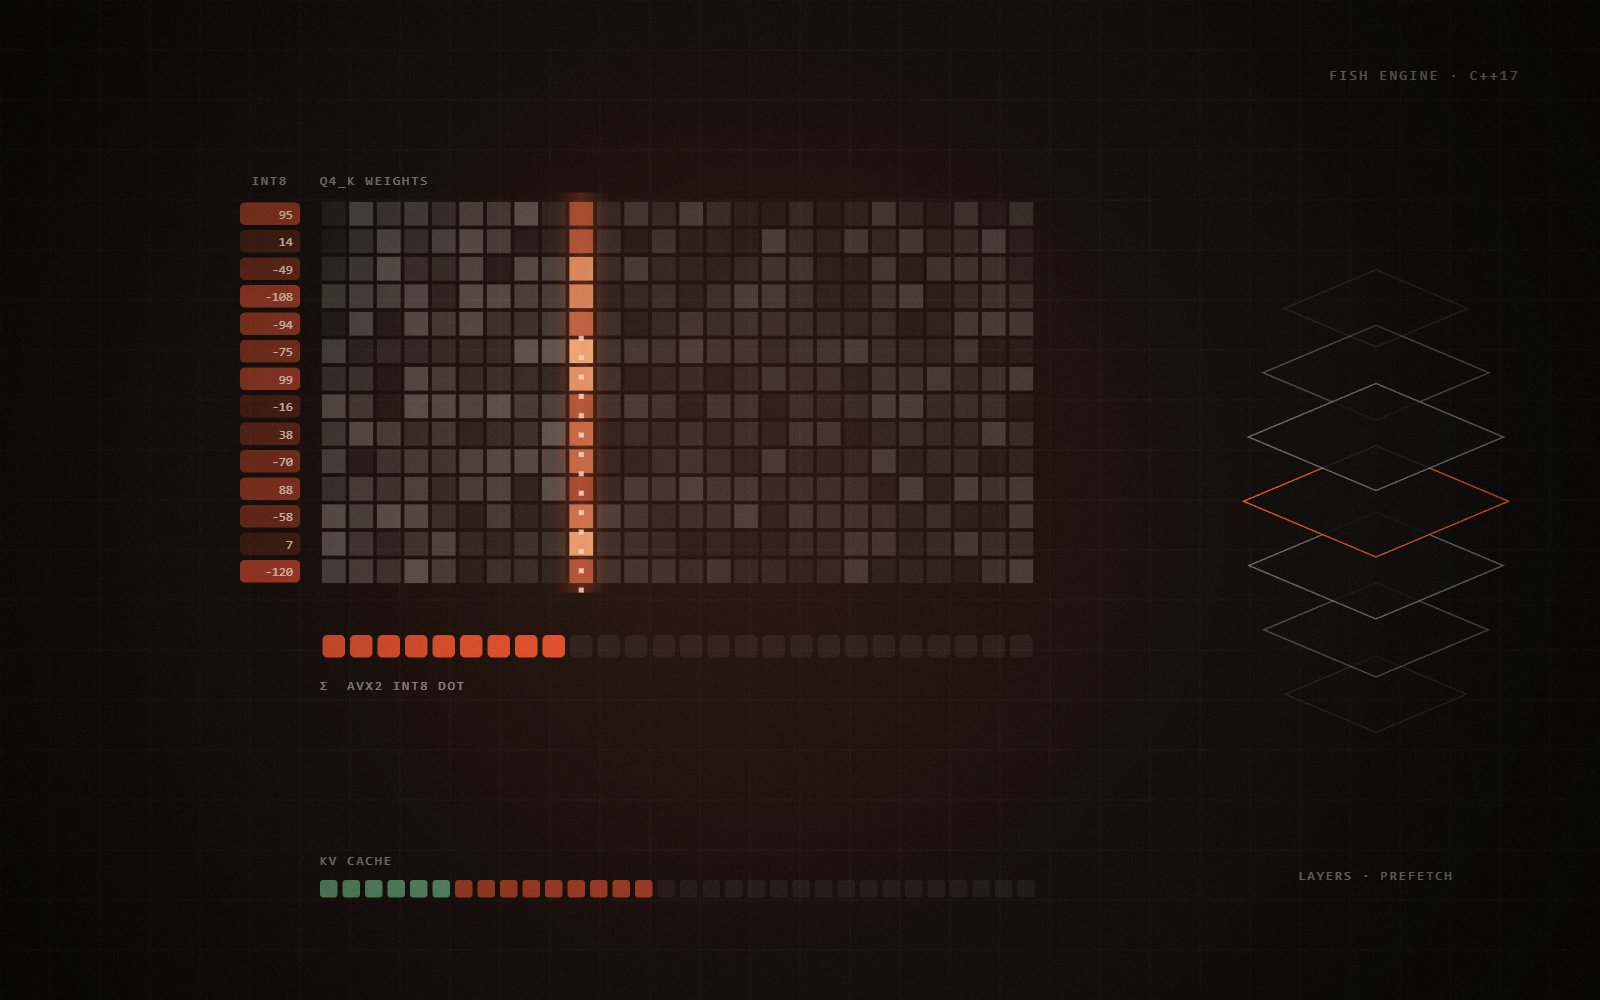
GGUF V2 · V3Activations are quantised to int8 once per matmul and run through AVX2 integer dot products, with a scalar reference kept as the oracle.
AVX2 · INT8Templates are applied structurally in the engine. Text a user types can never become a control token, and BOS is added exactly once.
NO INJECTIONA hardware probe measures cores, RAM and disk speed, then picks a context size that fits and decides which layers stay resident.
HW PROBEStep 1
The GGUF is memory-mapped and its tensors bound by architecture.
Step 2
The planner sizes the context and residency from the measured machine.
Step 3
The prompt runs as a batch, reusing any cached prefix.
Step 4
Tokens stream out one by one, cancellable at any point.
 01 / 06
Language
C++17, exposed through a C ABI
Memory-maps the model and keeps weights quantised
int8 activations with AVX2 integer kernels, scalar fallback elsewhere
Chat templates applied inside the engine, so user text cannot inject control tokens
A KV prefix cache makes repeated system prompts free
FROM IDEA TO RELEASE
Founder & maintainer
The founder’s storyOpen-source contributors
Fork the repoor just email support@imutechz.in