Step 1
More model families
Bring up Qwen 2.5, Qwen 3, Phi-3.5 and Gemma 2 with real files and record what breaks.
Our research goes into IMURUN: an inference engine, an agent and a research pipeline that run on your own machine. The code and the notes, including what does not work yet, are public.
Track 01 / 05 · Shipped
FISH is a C++ engine that runs GGUF language models on ordinary computers. No llama.cpp underneath: every kernel, the tokenizer and the planner are ours.
Explore FISH engine KERNELS
Our own C++ engine for running models locally
Explore → VULKAN
One portable backend for NVIDIA, AMD and Intel
Explore → APPROVE
Tools, permissions, approvals and sub-agents
Explore → SOURCES
Cleaned, ranked passages with numbered sources
Explore →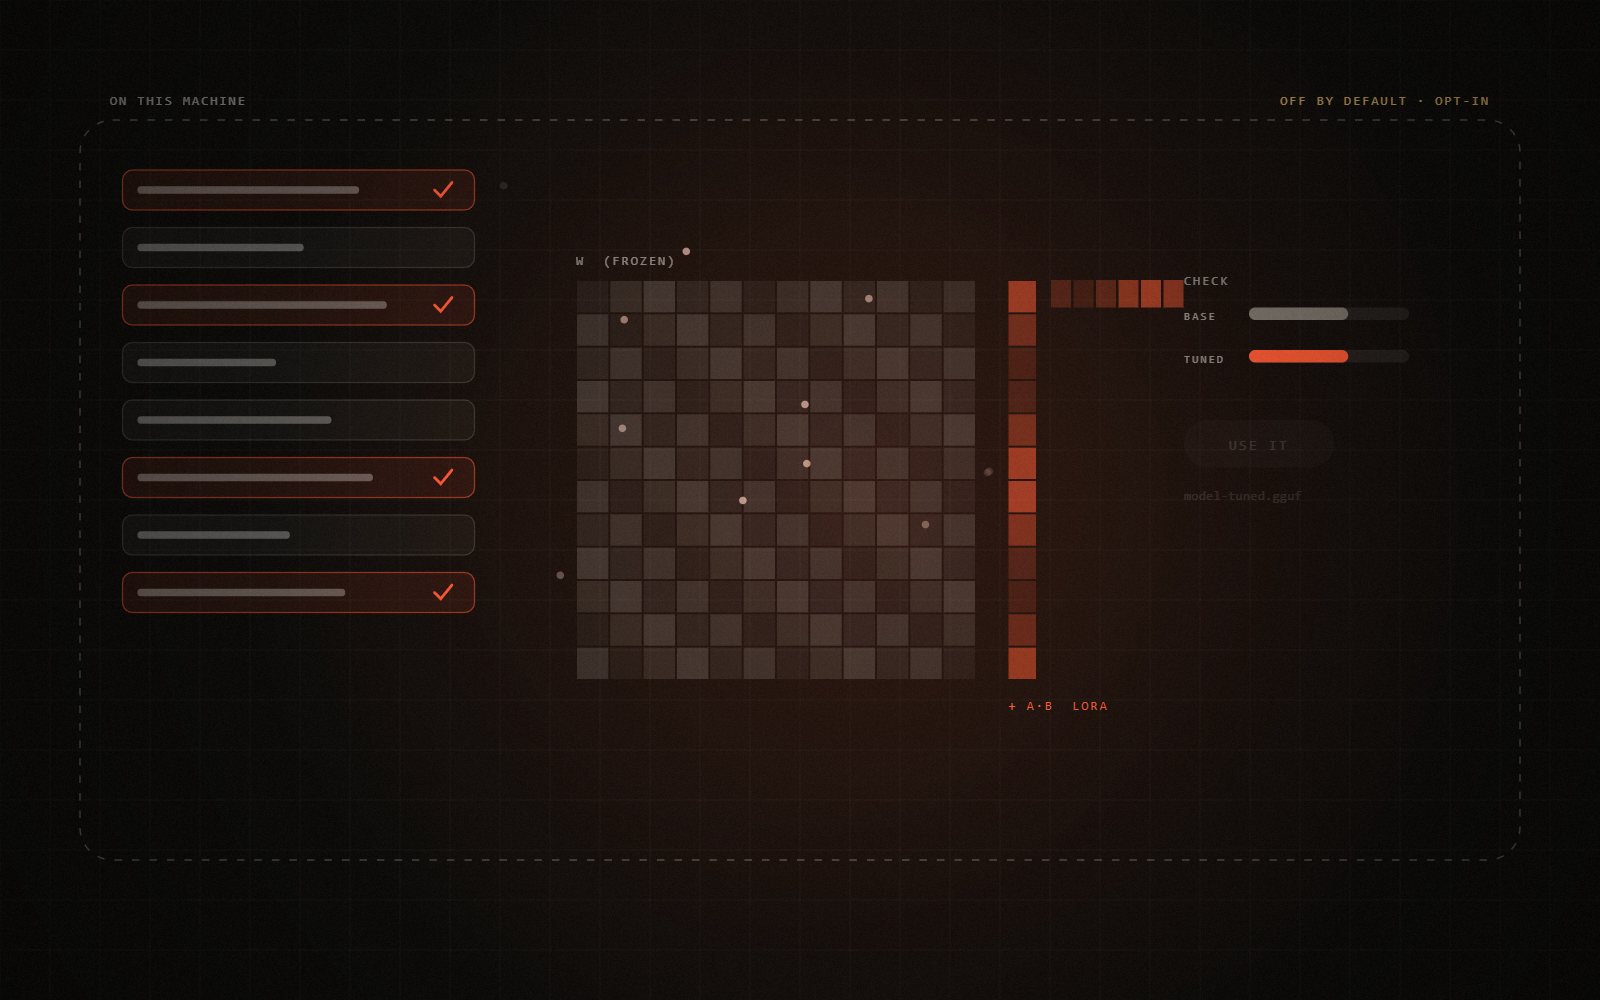 CONSENT
A model that learns from your feedback, locally
Explore →Step 1
Bring up Qwen 2.5, Qwen 3, Phi-3.5 and Gemma 2 with real files and record what breaks.
Step 2
Wider integer kernels on x86, and ARM NEON paths for Apple silicon and phones.
Step 3
An f16 KV cache for longer context, and 2–3-bit quant kernels for 4 GB devices.
Step 4
Load layers on a byte budget, so models larger than RAM stream predictably.
or just email support@imutechz.in, or open an issue on GitHub